
Why total Alone Can’t Tell You a Paginated List Hit Its LIMIT
Whether there's more data waiting is something no count can tell you — only fetching one row past the limit can.
Say you’re building an API that lists orders. It filters on a search condition, returns the matching orders as an array, and the screen wants a headline number too, something like “3,500 orders total.” Here’s the kind of implementation most people reach for first.
const MAX_LIMIT = 1000;

function listOrders(db, requestedLimit) {
  const limit = Math.min(requestedLimit, MAX_LIMIT);
  const items = db.prepare(
    "SELECT id FROM orders WHERE status = 'open' ORDER BY id LIMIT ?").all(limit);
  return { total: items.length, items };
}
The server caps how many rows a single request can return, 1,000 here, so a burst of results never blows up the response. That’s a perfectly ordinary design decision. Write a test for it the day you ship, and it passes: the count matches, nothing throws.
But there’s a gap hiding in this code. If 3,500 orders actually have status = 'open', the screen still reports “1,000 orders total.” Nobody filtered anything down, and no bug dropped a row. The number on screen and the number that actually exists have quietly come apart. So where did things go sideways?
Same Response, Two Very Different Truths
total in that snippet is items.length, the length of the array the server happens to send back. It isn’t counting the population: the total number of rows that actually match the condition. When there are fewer rows than the limit, nothing goes wrong. Once the population exceeds the limit, the story changes.
To see it happen, only one thing was varied: the row count in the database. With exactly 1,000 open orders, and again with 3,500, the same code was asked for limit=5000, a value above the cap.
for (const n of [1000, 3500]) {
  const res = listOrders(makeDb(n), 5000);
  console.log(`${n} rows in DB / requested limit=5000 ->`,
    JSON.stringify({ total: res.total, itemsLength: res.items.length,
      lastId: res.items.at(-1).id }));
}
1000 rows in DB / requested limit=5000 -> {"total":1000,"itemsLength":1000,"lastId":1000}
3500 rows in DB / requested limit=5000 -> {"total":1000,"itemsLength":1000,"lastId":1000}The two responses are identical, byte for byte: same total, same items length, same trailing id. A caller has no way to tell which of the two situations produced it. No error, no log entry: the 2,500 rows that got truncated away simply vanish.
Rounding the requested limit down to a server-side cap isn’t the problem by itself. That’s a common way to keep a response from ballooning, and the last section of this article comes back to it. The problem is that total never says the rounding happened.
There Are at Least Four Ways to Count “Total”
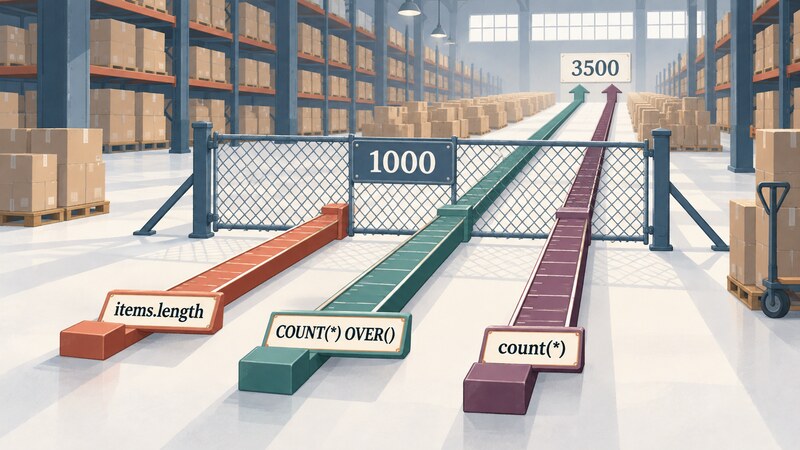
“Count the length of the array” is only one option for how total gets built. Four different approaches, including two done entirely in SQL, are worth lining up side by side. The population here is 5,000 rows, of which 3,500 have status = 'open', with a limit of 1,000.
-- (a) length of the returned array, computed in JS
SELECT id FROM orders WHERE status = 'open' ORDER BY id LIMIT 1000

-- (b) count the LIMITed result again
SELECT count(*) FROM (
  SELECT id FROM orders WHERE status = 'open' ORDER BY id LIMIT 1000
)

-- (c) a window function, COUNT(*) OVER (), in the same SELECT as LIMIT
SELECT id, count(*) OVER () AS total
FROM orders WHERE status = 'open' ORDER BY id LIMIT 1000

-- (d) a separate query
SELECT count(*) FROM orders WHERE status = 'open'
(a) items.length = 1000
(b) count(*) of LIMITed subquery = 1000
(c) count(*) OVER () with LIMIT = 3500 (rows returned: 1000)
(d) separate count(*) query = 3500(a) and (b) both count after the cut, so both land on the limit itself, 1,000: different code, same trap. (c) and (d) count the population that matches the condition, and both correctly return 3,500.
What makes (c) interesting is that COUNT(*) OVER () sits in the very same SELECT as LIMIT 1000. So how does it see past the cutoff? OVER (...) defines a window, the slice of rows a function aggregates over, which is why this is called a window function. Put PARTITION BY inside the parentheses and you split rows into groups; leave it empty, as here, and the window becomes every row that matched the condition, counted as one group.
PostgreSQL’s own documentation explains why window functions can’t appear in WHERE or GROUP BY.
Window functions are permitted only in the SELECT list and the ORDER BY clause of the query. They are forbidden elsewhere, such as in GROUP BY, HAVING and WHERE clauses. This is because they logically execute after the processing of those clauses.
Window functions are evaluated after WHERE has already filtered rows. The docs for SELECT itself lay out the same ordering: the output rows, window functions included, are computed before ORDER BY, and LIMIT/OFFSET come after that.
If the ORDER BY clause is specified, the returned rows are sorted in the specified order. … If the LIMIT (or FETCH FIRST) or OFFSET clause is specified, the SELECT statement only returns a subset of the result rows.
That ordering is exactly why COUNT(*) OVER () can report the population before LIMIT throws rows away: one query hands back both the true total and the capped page. It sounds like a free lunch, but it has a character of its own, which the next section gets into.
Comparing How to Detect It, and How to Fix It
How do you actually catch a truncated list? The candidates are on the table already: count the population in a separate query, fold COUNT(*) OVER () into the same query, or give up on the total entirely and report only whether there’s more. Each one comes with a tradeoff worth measuring.
A Separate count(*) Query: Accurate the Moment You Ran It
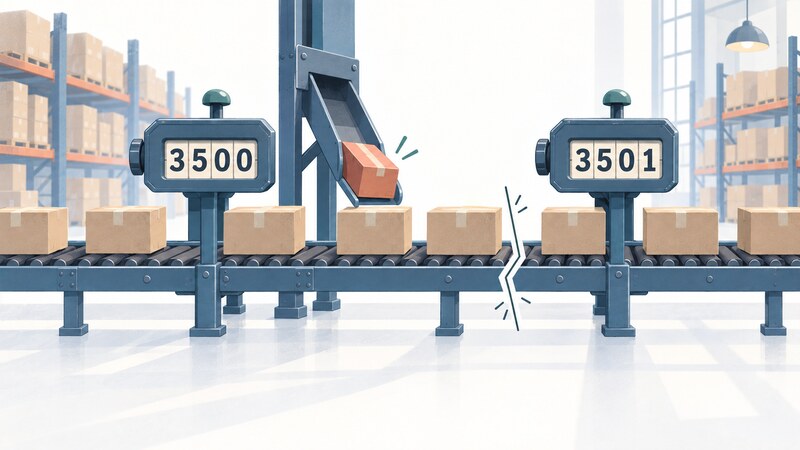
The most obvious fix is swapping total for a count(*) from a second query. It has a catch that’s easy to miss: if rows are inserted or deleted between the moment you counted and the moment you finish paging through, the number drifts.
To see it, 3,500 rows were counted first, then, before the list was paged through, one more row was inserted by someone else, then every page was fetched to the end.
const total = db.prepare("SELECT count(*) AS c FROM orders WHERE status = 'open'").get().c;
// Right after counting, before the list is fetched, another user inserts one row
db.prepare("INSERT INTO orders(status) VALUES ('open')").run();
// Page through every page at page size 1000 (code omitted)
total (counted first) = 3500, rows actually fetched by paging to the end = 3501The counted total stayed at 3,500, but paging all the way through actually pulled back 3,501 rows. The separate count(*) query isn’t lying: it’s telling you exactly the value at the moment it ran. Pagination spans multiple requests, so it has no way to account for what changes in between.
COUNT(*) OVER (): One Query, but It Vanishes the Moment Zero Rows Come Back
COUNT(*) OVER () rides along with every row it returns, which means that if zero rows come back, the total disappears with them. Here’s what actually happens once OFFSET runs past the end of the result set.
SELECT id, count(*) OVER () AS total
FROM orders WHERE status = 'open' ORDER BY id LIMIT 1000 OFFSET :offset
OFFSET 3000 -> rows 500, total = 3500
OFFSET 3500 -> rows 0, total = (no row to read it from)
OFFSET 4000 -> rows 0, total = (no row to read it from)At OFFSET 3000, the remaining 500 rows arrive with total = 3500 riding along. Once OFFSET runs past the population, though, zero rows come back, and with them goes the only place total had to attach itself. What a caller does with total on the page past the last one is something that has to be decided separately; the value simply isn’t there to read.
There’s a second surprise here, this time about cost. The instinct is that fewer round trips must mean COUNT(*) OVER () wins, so it was timed against a separate count(*) on a million-row table with an index in place.
LIMIT 1001 (limit + 1)           median 0.60 ms
count(*) OVER () + LIMIT 1000    median 789.43 ms
separate count(*) query          median 61.87 ms
That instinct was wrong. COUNT(*) OVER () came in an order of magnitude slower than a plain count(*), roughly 12 to 13 times slower across two separate runs. The execution plan, the step-by-step strategy the database actually uses to run a query, visible in SQLite by prefixing a query with EXPLAIN QUERY PLAN, explains why.
count(*) OVER () + LIMIT 1000: CO-ROUTINE (subquery-2) / SEARCH orders USING COVERING INDEX idx_orders_status_id (status=?) / SCAN (subquery-2) / USE TEMP B-TREE FOR ORDER BY
separate count(*) query: SEARCH orders USING COVERING INDEX idx_orders_status_id (status=?)
The window-function version has to materialize every matching row as a subquery first, then re-sort them in a temporary B-tree to satisfy ORDER BY. The plain count(*) just walks the index and counts: no row materialization, no sort. Fewer round trips doesn’t automatically mean less work.
This is one measurement in one environment, SQLite 3.47.0 (the version bundled with Node.js v22.12.0), a million rows, one index, and the absolute numbers move between runs (735 to 789 ms across two measurements). Still, the order held both times: of the two ways to get a real total, the separate count(*) was the lighter one, and COUNT(*) OVER () was the heaviest. The fastest option, LIMIT 1001, doesn’t count a total at all; that’s the pattern coming up next. It’s worth checking the execution plan in your own environment rather than assuming “fewer queries” always means “faster.”
Fetch limit + 1 Rows: Give Up on “How Many” and Learn “Is There More”
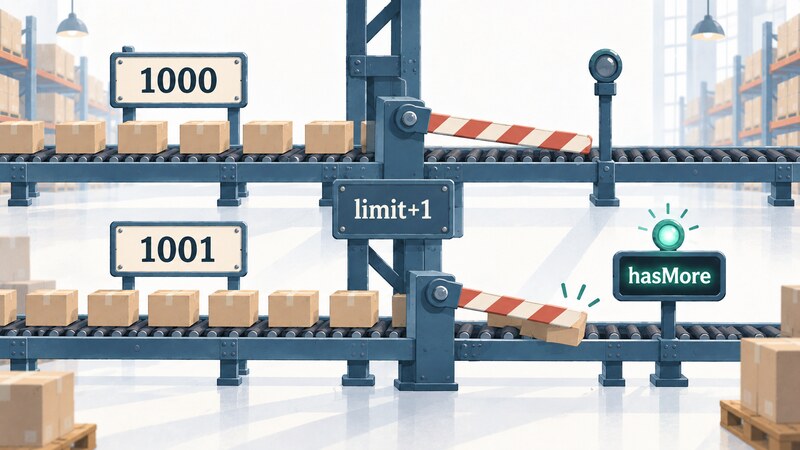
There’s also the option of abandoning the total altogether. Fetch one row more than the limit, and use whether that extra row showed up to decide whether there’s more data, nothing else.
const LIMIT = 1000;

function listOrders(db) {
  const rows = db.prepare(
    "SELECT id FROM orders WHERE status = 'open' ORDER BY id LIMIT ?").all(LIMIT + 1);
  const hasMore = rows.length > LIMIT;
  const items = hasMore ? rows.slice(0, LIMIT) : rows;
  return { items, hasMore };
}
Run it across the boundary and the split is clean: right at the limit, hasMore is false; one row over, it flips to true.
   0 rows in DB -> items    0, hasMore=false
 999 rows in DB -> items  999, hasMore=false
1000 rows in DB -> items 1000, hasMore=false
1001 rows in DB -> items 1000, hasMore=true
3500 rows in DB -> items 1000, hasMore=true
There’s one more thing worth checking here. A tempting shortcut is to say that if the returned count equals the limit, it might have been truncated. Without a population count in hand, that looks like a reasonable fallback.
But the shortcut misfires exactly when the population happens to equal the limit. Look at the row for 1,000 real rows: the population lands exactly on the boundary, yet “count equals limit” fires anyway. Actually fetching limit + 1 rows resolves that boundary correctly along with everything else; one extra row is all it costs to avoid the false positive.
limit + 1 tells exactly-at-the-limit apart from one-over by a single itemSignaling “More” with a Next-Page Token
limit + 1 is a lightweight pattern you can build yourself, but public APIs tend to go one level more abstract. Google’s API design guidance, AIP-158, is explicit about how list APIs should handle pagination.
The API may return fewer results than the number requested (including zero results), even if not at the end of the collection.
If the end of the collection has been reached, the next_page_token field must be empty. This is the only way to communicate “end-of-collection” to users.
The key move is that “is there more” is never decided by counting rows. A response shorter than what was asked for doesn’t by itself mean the end of the collection, per the first quote. The one and only signal for “you’ve reached the end” is whether the next-page token comes back empty, per the second. Instead of relying on how many rows came back, the design relies on a single flag: whether a token is present.
The same document is equally clear about the total-count field itself.
Response messages for collections may provide an int32 total_size field, providing the user with the total number of items in the list.
total_size is a “may,” not a “must.” The pagination-ends signal is carried entirely by the next-page token. This article doesn’t walk through a next-page-token implementation in code; the point worth taking away is the design principle itself: separate “how many total” from “have you reached the end” into two different mechanisms.
A Playbook for Both Sides of the API
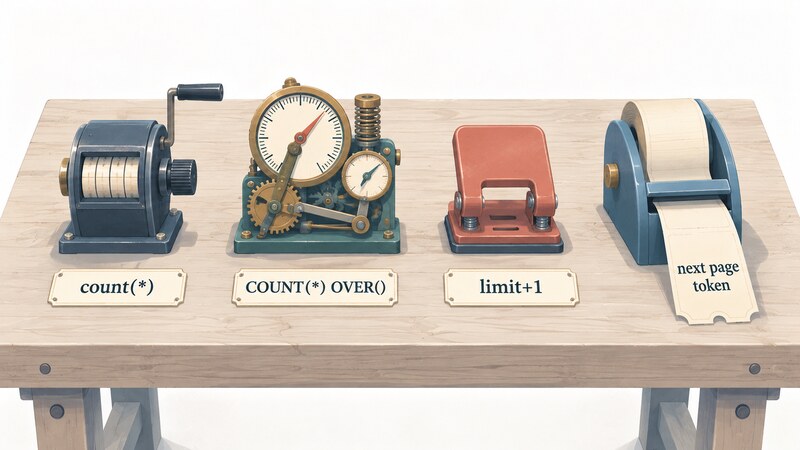
Lined up, the four approaches each have a clear strength and a clear weakness.
| Approach | Accuracy of the total | Cost | Detecting “is there more” | Confirmed by |
|---|---|---|---|---|
Array length / count after LIMIT |
Wrong once truncated | No extra cost | Can’t | Measured |
Separate count(*) query |
Accurate at the moment counted, drifts afterward | Moderate | Needs something like limit + 1 on top |
Measured |
COUNT(*) OVER () |
Accurate, unless zero rows come back | Heaviest in this environment | Needs something separate | Measured |
limit + 1 with hasMore |
Doesn’t tell you the total | Nearly free | Accurate, including at the boundary | Measured |
| Next-page token | Optional (total_size is a “may”) |
Depends on the implementation | Presence or absence of the token | From the spec |
That leaves one takeaway for each side of the API.
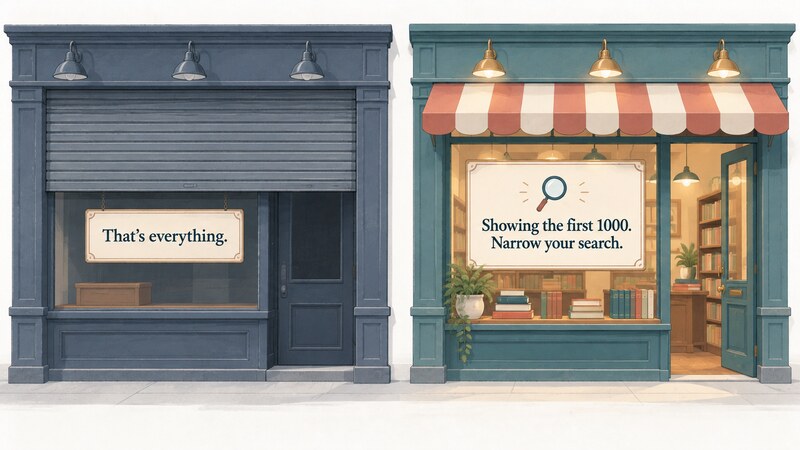
If you’re building a list API, once you know you’ve hit the limit, say so in plain language on the screen. Instead of “that’s everything,” something closer to “showing the first 1,000, narrow your search” hands the possibility of truncation straight to the person using it. And when total shows up in an API contract, document exactly where it’s counted, population or rows returned, because the field name alone never tells a caller which one it is.
If you’re calling a list API, it helps to assume your requested limit might get silently rounded down. Both AIP-158 and GitHub’s REST API docs are explicit that requesting more than the maximum page size isn’t an error; it just gets capped.
If the user specifies page_size greater than the maximum permitted by the API, the API should coerce down to the maximum permitted page size.
If you specify a value greater than the maximum, GitHub does not return an error. Instead, the value is automatically reduced to the maximum
Capping the limit is a legitimate design choice; multiple public APIs do exactly this. What matters isn’t the capping itself but whether there’s a signal for “there’s more” alongside it. An API that caps silently and offers no such signal has the same gap as the snippet at the top of this article.
Takeaways
total is the same field name everywhere, but what it means depends entirely on where it was counted. items.length, and count(*) run on an already-LIMITed result, only ever see inside the cap. COUNT(*) OVER () and a separate count(*) both reach the real population, each with its own catch: one disappears when zero rows come back, one is only accurate the instant it ran, and in this environment one turned out to be noticeably heavier than expected.
Give up on the total and fetch limit + 1 instead, and you get a correct “is there more,” boundary case included, at almost no extra cost. Go one step further and there’s the next-page-token pattern AIP-158 defines: signal the end with a flag, not a count.
Next time you look at a list API’s total, it’s worth checking exactly where that number came from. If the answer isn’t immediate, that total may not be telling you anything yet.
Primary Sources
- PostgreSQL docs — Queries: LIMIT and OFFSET (that
LIMITreturns “at most” that many rows, and whyORDER BYis needed for a deterministic result) - PostgreSQL docs — SELECT (the processing order of a
SELECT;LIMIT/OFFSETare applied afterORDER BY) - PostgreSQL docs — Tutorial: Window Functions (window functions are evaluated after
WHERE/GROUP BY/HAVING) - Google AIP-158: Pagination (capping
page_size,total_sizeas an optional field, signaling the end of a collection with a next-page token) - GitHub Docs: Using pagination in the REST API (a real-world example of capping an over-the-maximum value)